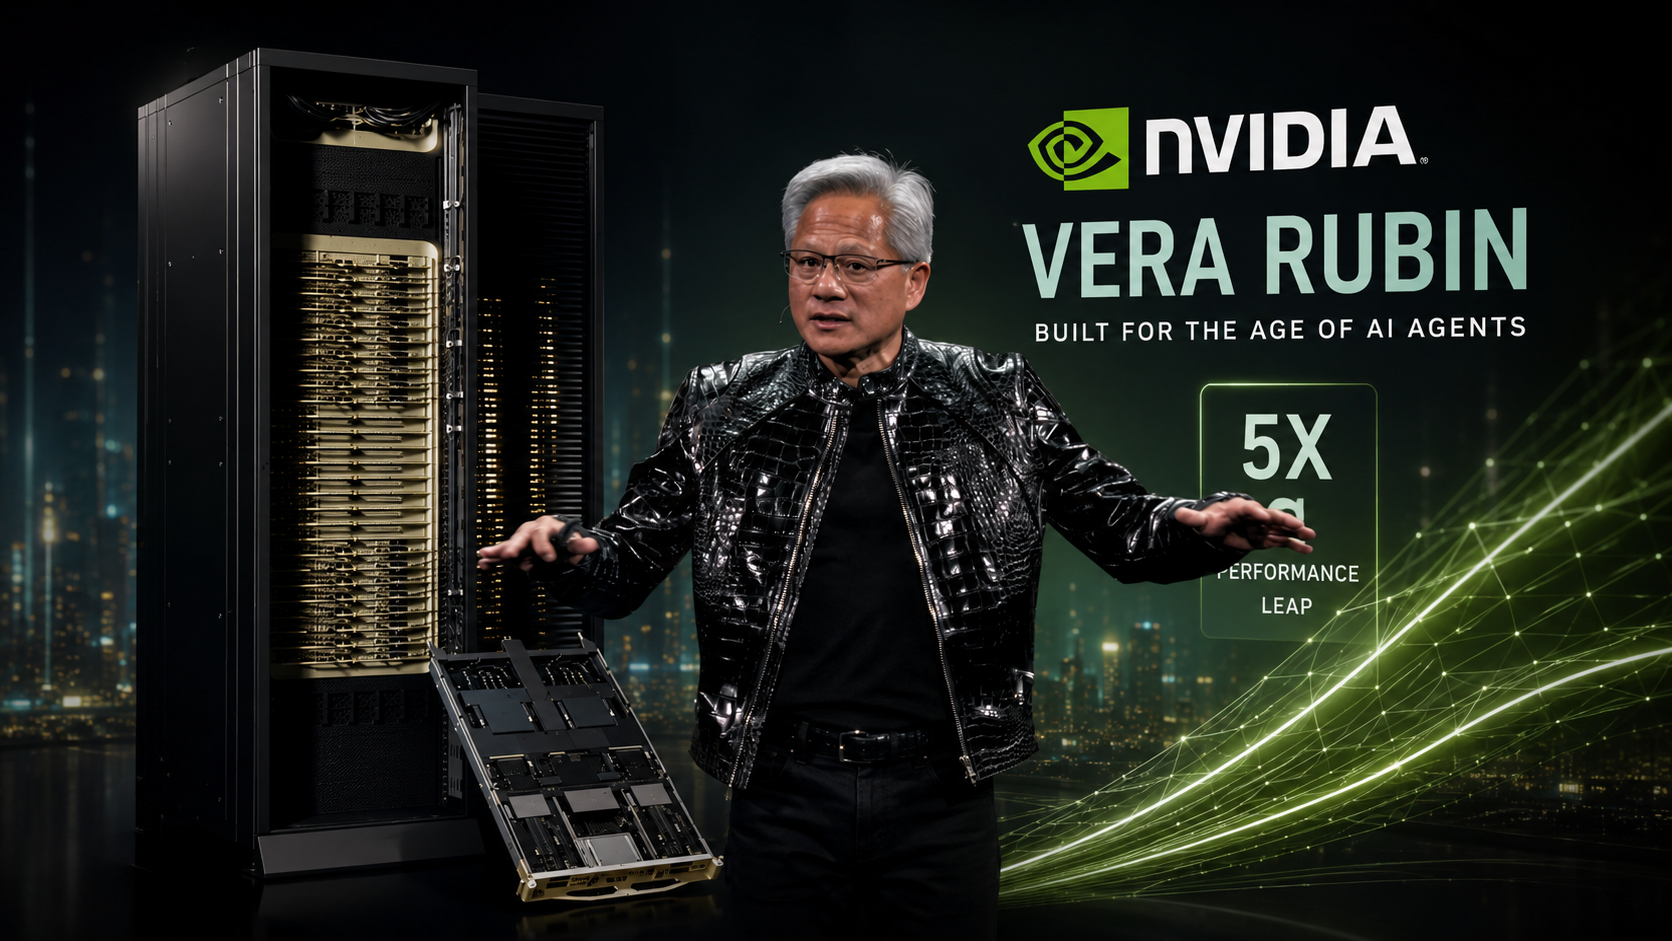
Nvidia has formally launched Vera Rubin, the next generation of its artificial intelligence computing platform, announcing at CES 2026 in Las Vegas that the system is in full production with partner products expected in the second half of the year. The platform pairs a new Vera central processing unit with two Rubin graphics processing units in a single package and forms the centerpiece of an ambitious effort to redefine the economics of the data centers that power modern AI. With the company positioning Rubin as purpose-built for agentic AI, advanced reasoning models, and the increasingly popular mixture-of-experts architectures, the launch reflects how thoroughly the latest wave of AI development is reshaping the demands placed on computing infrastructure.
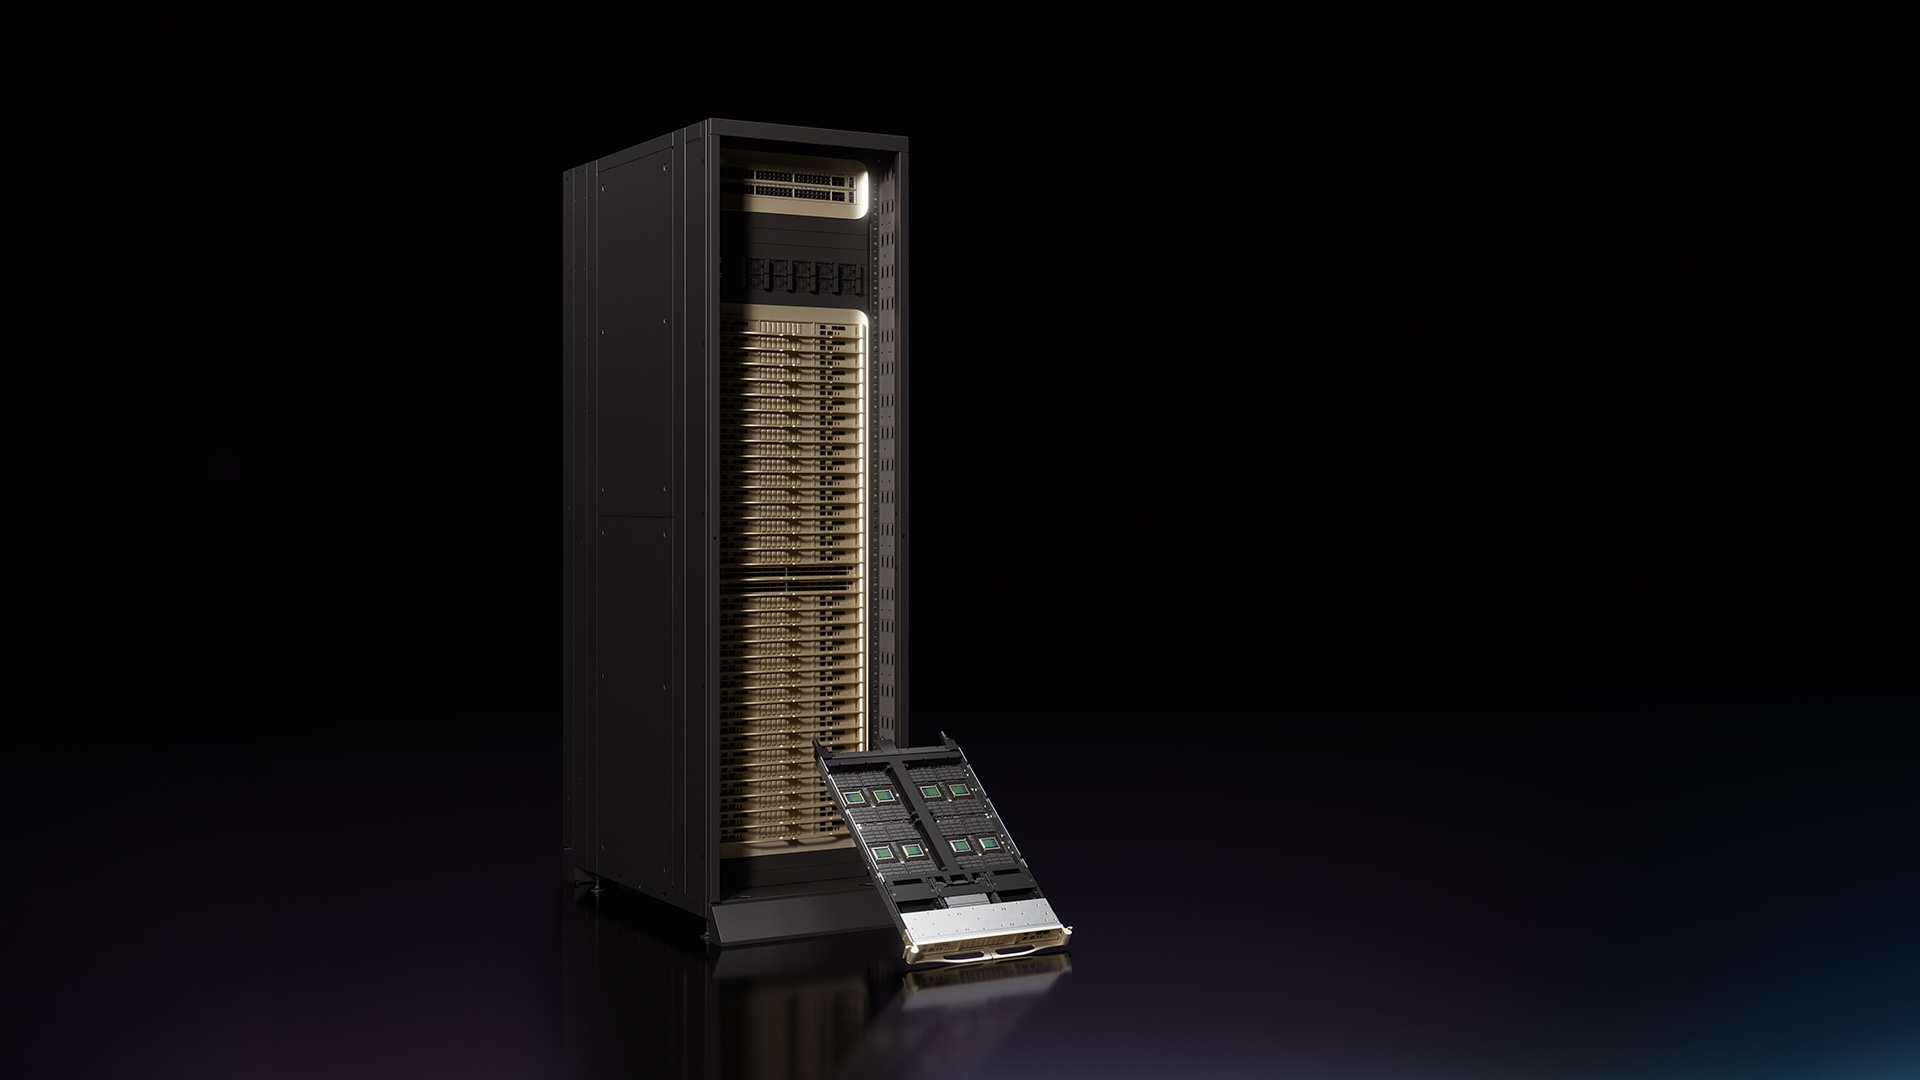
The technical specifications Nvidia has disclosed are striking in their ambition. Each Rubin GPU is built from roughly 336 billion transistors, delivers around 50 petaflops of performance, and carries 288 gigabytes of HBM4 memory, the latest generation of high-bandwidth memory designed to feed data-hungry AI workloads. At the platform level, Nvidia claims that Vera Rubin offers approximately five times the inference performance of its current Blackwell generation while reducing the cost per token, a key measure of efficiency for AI systems, by as much as a factor of ten. If these figures hold up in real-world deployments, they would represent a substantial generational leap at a moment when the cost of running large AI models has become one of the industry’s most pressing concerns.
Rubin is not a single chip but a family of six, reflecting Nvidia’s strategy of selling integrated systems rather than discrete components. Alongside the Vera CPU and Rubin GPU, the platform includes the NVLink 6 Switch for high-speed interconnection, the ConnectX-9 SuperNIC and Spectrum-6 Ethernet Switch for networking, and the BlueField-4 data processing unit for offloading infrastructure tasks. This systems-level approach has been central to Nvidia’s dominance, since it allows the company to optimize performance across the entire stack and makes its platforms difficult for customers to disaggregate or replace piecemeal. By controlling so many of the components that make up an AI data center, Nvidia has built a position that competitors have found challenging to dislodge.
The choice to frame Rubin around agentic AI and reasoning models is revealing of where the industry believes value is migrating. Where earlier generations of AI infrastructure were optimized largely for training ever-larger models, the emphasis has increasingly shifted toward inference, the process of actually running models to serve users, and particularly toward the demanding workloads created by systems that reason through multiple steps or coordinate multiple specialized components. Mixture-of-experts models, which route each query to the most relevant subset of a larger network, are especially well suited to the kind of efficiency gains Nvidia is promising, and the company’s explicit targeting of these architectures suggests a careful read of where its largest customers are heading.
Those customers represent a roster of the most significant names in cloud computing. Nvidia indicated that among the first to deploy Vera Rubin-based systems would be Amazon Web Services, Google Cloud, Microsoft, and Oracle Cloud Infrastructure, alongside specialized AI cloud providers such as CoreWeave, Lambda, Nebius, and Nscale. The breadth of this early adoption underscores the extent to which the major cloud platforms remain dependent on Nvidia’s hardware even as several of them invest heavily in developing their own custom AI chips, a dynamic that speaks to both the strength of Nvidia’s position and the intensity of the competition it will eventually face.
The launch also arrives against a backdrop of extraordinary demand and persistent questions about the sustainability of AI infrastructure spending. The enormous capital being directed toward data centers has prompted debate about whether the returns will justify the investment, and Nvidia’s promise of dramatically lower cost per token can be read in part as a response to those concerns, offering customers a path to better economics even as absolute spending continues to climb. Whether the efficiency gains translate into the broad profitability that the industry’s investments presuppose remains an open and consequential question.
For all the impressive specifications, the ultimate test of Vera Rubin will be its performance in the hands of the cloud providers and enterprises that deploy it later in the year, and prudence suggests treating vendor-supplied benchmarks as starting points rather than settled conclusions. Even so, the launch is a clear statement of Nvidia’s intent to remain at the center of the AI computing era it has done so much to define. As reasoning models and autonomous agents place ever-greater demands on infrastructure, the platforms that can deliver more capability at lower cost will shape what becomes possible, and with Vera Rubin, Nvidia has once again set the terms of that conversation.